Solutions
Audio & Image
Multimodal data for a more intelligent world.
Sentious helps teams collect, annotate, and evaluate audio and image data at scale — from speech and soundscapes to images and video.
The platform
A unified workspace
for audio and image data.
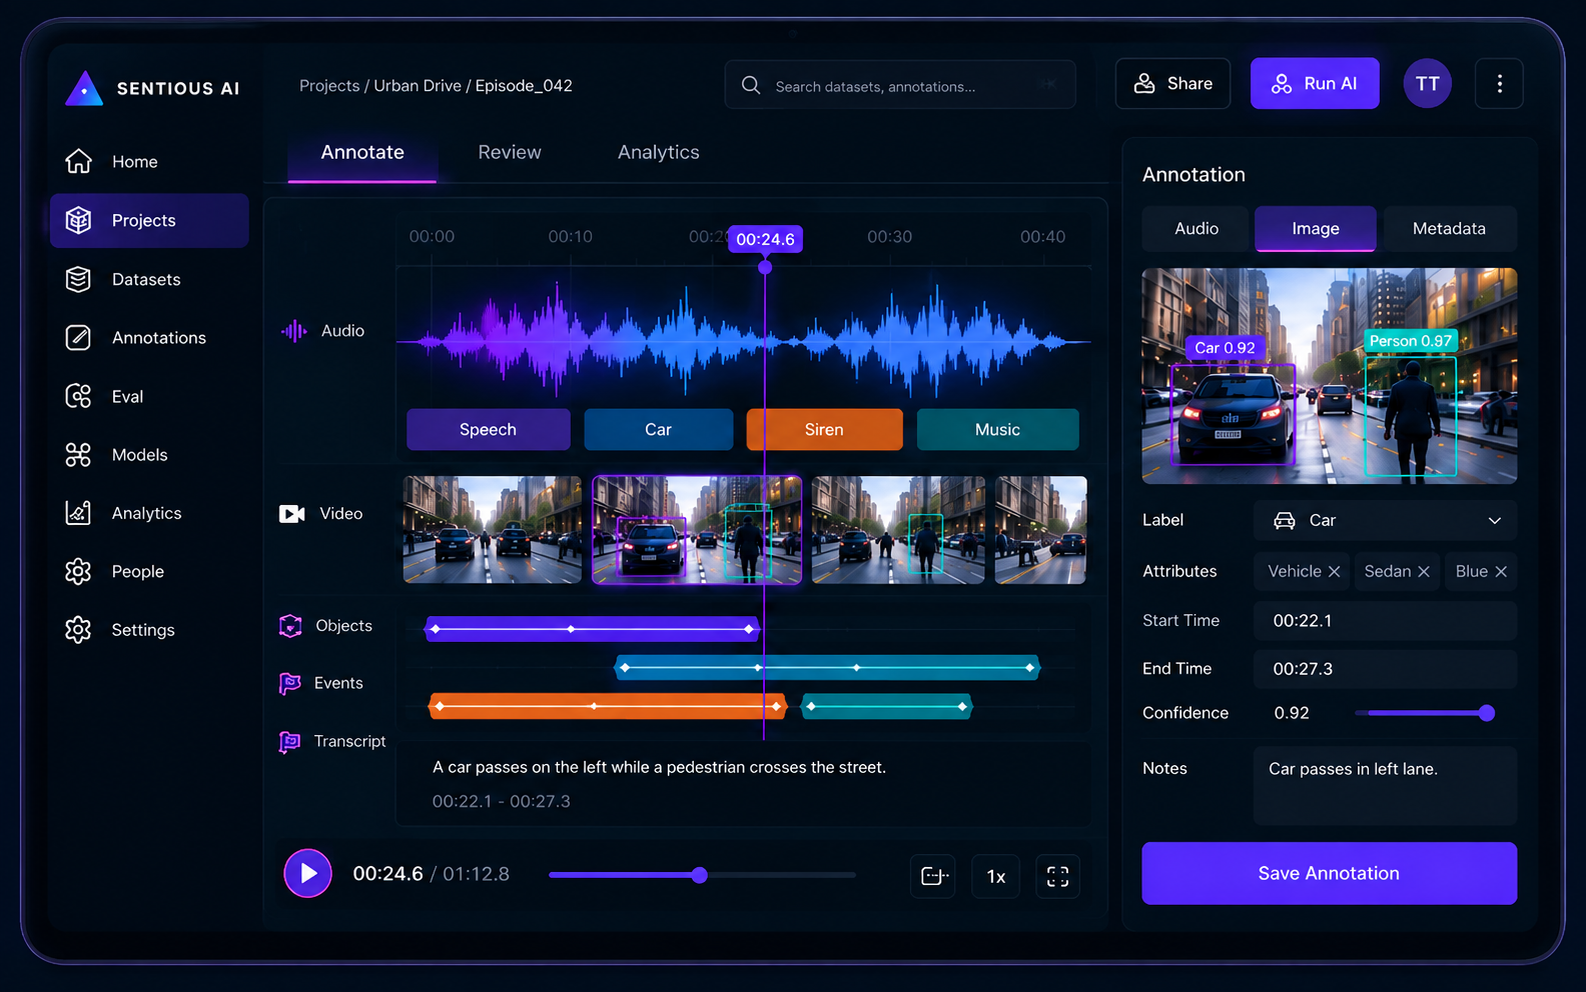
One system aligns audio, imagery, events, metadata, annotations, and review decisions against the same underlying timeline and dataset.
- Audio transcription and event labeling
- Image annotation with rich metadata
- Multimodal synchronization
- Built-in QA and review workflows
- Scales from research to production
Tools for every modality.
Specialized workflows for audio and image — each with the depth its modality demands, all in one platform.
Audio Annotation
- Transcription
- Speaker diarization
- Sound event labeling
- Music and noise tagging
Image Annotation
- Bounding boxes
- Semantic segmentation
- Keypoint annotation
- Attribute labeling
Multimodal Sync
- Shared timeline
- Audio–frame alignment
- Event anchoring
- Cross-modal search
Quality & Review
- Review queues
- Consensus scoring
- Audit trails
- Feedback loops
Use cases
From real-world data
to real-world impact.
The same multimodal foundation, applied wherever sound and vision meet.
Better data. Broader intelligence.
Audio and image data
work better together.
Sound gives vision context; vision gives sound meaning. Aligned on one timeline, they teach models what the world is actually like.
Free to StartTrusted by innovators
Powering the next generation
of multimodal AI.
Get started
Turn your audio
and image data into progress.
High-quality multimodal data. A more capable world.